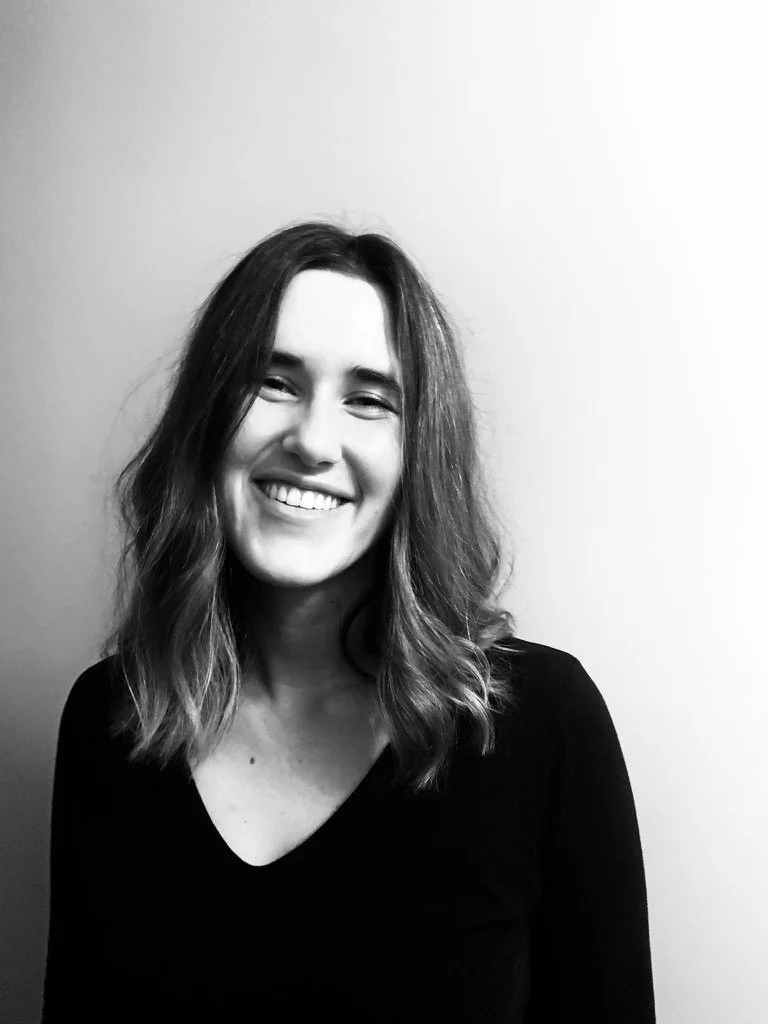
Jeanne has been building language models since before it was cool.
With nearly ten years of experience in language modelling and data science, spanning both industry and research, her focus has always been on multilingual and low-resource settings, where data is scarce, noisy, and rarely benchmark-ready. Her work has spanned healthcare, misinformation detection on social media, and real-world language understanding in underrepresented languages, with privacy and data protection as a consistent consideration throughout. More recently, her interests have extended into finance, specifically how language models can be used to extract signal from social media and news to model and anticipate market behaviour.
Her research has been published at ACL, including work on automating multilingual healthcare question answering in low-resource African languages. She approaches problems at the intersection of language, people, and systems, with a particular interest in making AI work in contexts it was never (or not yet) designed for.
Outside of work, she reads widely across behavioural economics, climate change, and misinformation and writes occasionally when something is worth saying.
Originally from Cape Town, Jeanne now lives in England with her husband and two Bengal cats, Eira and Kinzy.
Blog
Benchmaxxing: The ugly art of optimising for leaderboards rather than real-world performance
In 2015, Volkswagen was caught running software that detected when a car was being emissions-tested and switched the engine into a compliant mode for the duration of the test. The AI industry is running a version of the same pattern, at scale, largely unchallenged.
Vibe-Coding: A Double-Edged Sword
Vibe coding has collapsed the distance between having an idea and having a working app. For prototyping, it's genuinely transformative. But the gap between a convincing demo and production-ready software hasn't closed — and the judgment required to bridge that gap hasn't gotten any cheaper to acquire.
How the Best AI Companies Use Data to Build Unbeatable Moats
Data doesn't scale linearly — it compounds. Here's how companies like OpenAI and Google use virtuous data cycles and network effects to build moats that are almost impossible to compete with.
Taking Stock of The AI Landscape - 2 Years since ChatGPT Launched
2 years ago, ChatGPT took the world by storm, being the first true conversational agent. This blog post explores the changes to the AI landscape since, from new competitors to litigation about copyright infringement.
Did Ronaldo Really Crash Coca-Cola’s Share Price?
On 14 June 2021, major news outlets around the world attributed a 1.6% drop in Coca-Cola’s share price to Cristiano Ronaldo’s preference of water over Coke. The truth was both a little more simple and a lot more complicated.
A Pre-mortem on the Meme Stock Bubble
Fee-free trading platforms, like Robinhood, made it very easy for novice investors to get started with their trader journey. Investors started to coordinate their efforts on Wall Street Bets, implemented short squeezes on dead-beat stocks like GameStop and the rest is history. This article explores the Meme Stock Bubble and the factors that influenced it.
Word Embeddings Explained: From Word2Vec to BERT and Beyond
Word embeddings models language by constructing dense vector representations of words that capture meaning and context, to be used in downstream tasks such as question-answering and sentiment analysis. This article explores the challenges of modelling languages, as well as the evolution of word embeddings, from Word2Vec to BERT.
Transformers: Age of Attention
In 2017, Google Brain researchers published a paper titled "Attention Is All You Need" and quietly changed the trajectory of AI. The Transformer architecture it introduced, built entirely on attention with no recurrence or convolutions, is the foundation of every large language model in use today. Here's how it actually works, from sequence-to-sequence models to multi-head attention.
Amazon’s Meteoric Rise
This article explores the key components of Amazon’s business model that led to them becoming a trillion dollar company, as well as some of the criticism that has been levelled against it.
The DotCom Bubble
Following the burst of the DotCom bubble, the surviving companies like Apple, Google, and Microsoft became apex predators in their respective fields. This article explores the factors leading up to and during the DotCom bubble, as well as examine the long-term impact on the tech ecosystem.